Cleaning Currency Values: Symbols, Thousands Separators and Negative Amounts
Parse messy money columns in DuckDB SQL and pandas: extract the currency, handle locale separators, fix negatives like (250.00) and store exact decimals.
By Tnas · Published · 11 min read
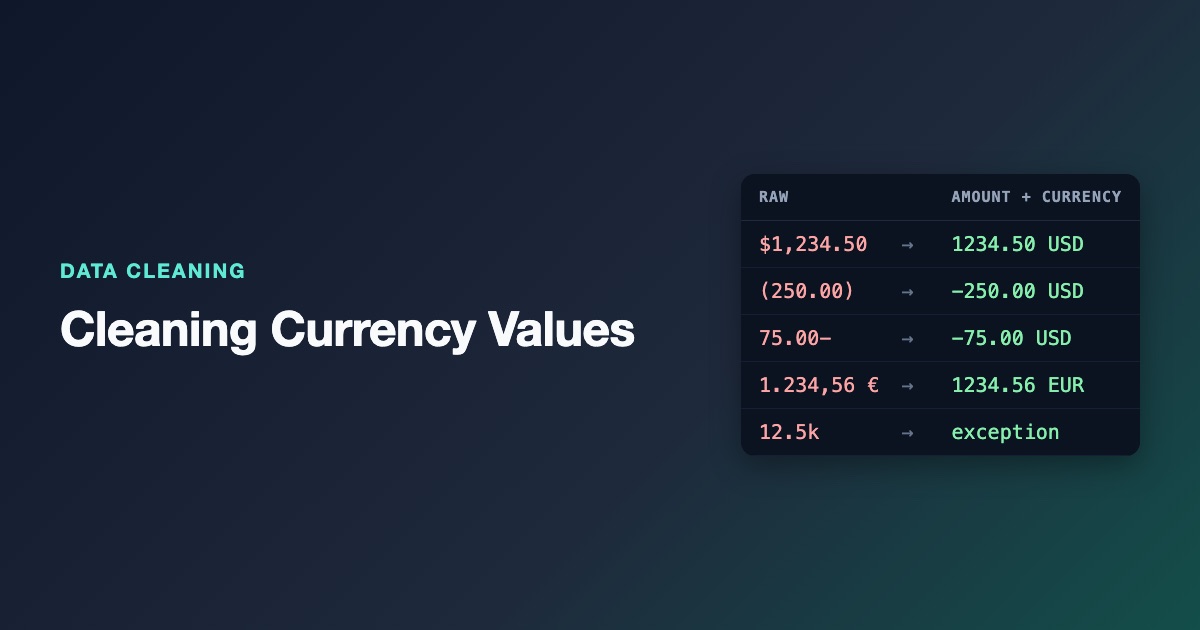
To clean currency values, read the column as text and split each value into two things: a currency code and an exact decimal amount. Take the currency from an explicit code or symbol, or from the file's declared currency. Turn every negative notation, such as (250.00), 75.00- and the Unicode minus sign, into a leading minus. Remove thousands separators using the source's declared number format, because 1,234 is one thousand two hundred and thirty-four in a US file and one point two three four in a German one. Then validate the shape and cast to a DECIMAL, never a float. Values that don't fit, like 12.5k, are reported rather than guessed. Below, the same rules run in DuckDB SQL and in pandas on thirteen messy values from three sources.
Key Takeaways
- A money value is two fields: an amount and a currency. Store them in separate columns and never add amounts across currencies.
- The decimal separator is a property of the source, not of the value. Declare it per file or per system; you can't infer it from
1,234.- Accounting exports show negatives in at least four ways: a leading minus, parentheses, a trailing minus and the Unicode minus sign
−. Normalize all of them before casting.- Validate the cleaned text against the expected number shape before casting, or a value like
12.5kquietly becomes12.5.- Use exact decimals (
DECIMALin DuckDB, a decimal Arrow type in pandas) so totals reconcile to the cent.
Why money columns arrive messy
Money columns are usually formatted for people, not machines. A spreadsheet adds a currency symbol and thousands separators, an accounting system writes refunds in parentheses, an ERP export puts the minus sign at the end, and a European shop uses a comma for decimals and a point or a space for thousands. Unicode's locale data (CLDR) gives 1’234,5 as one regional style, with an apostrophe for grouping and a comma for the decimal (Unicode CLDR, Number symbols). Same number, very different text.
None of that formatting is wrong in its own system. It only becomes a problem when files from several systems land in one table and someone runs SUM().
The messy column
Thirteen values from three sources. Each source has a declared locale (en means a point for decimals and a comma for thousands; de means a comma for decimals and a point or space for thousands) and a declared default currency. Those declarations come from whoever owns the files; they're inputs to the rule, not guesses.
| id | source | locale | file currency | amount_raw | What's going on |
|---|---|---|---|---|---|
| R01 | us_ledger | en | USD | $1,234.50 |
Symbol and thousands separator |
| R02 | us_ledger | en | USD | (250.00) |
Accounting negative |
| R03 | us_ledger | en | USD | 75.00- |
Trailing minus |
| R04 | us_ledger | en | USD | −12.40 |
Unicode minus sign (U+2212) |
| R05 | us_ledger | en | USD | 1,234 |
Comma is a thousands separator |
| R06 | de_shop | de | EUR | 1,234 |
Same text, comma is the decimal |
| R07 | de_shop | de | EUR | 1.234,56 € |
Point for thousands, symbol after |
| R08 | de_shop | de | EUR | -1 234,56 EUR |
Narrow no-break space for thousands |
| R09 | uk_shop | en | GBP | £ 99 |
Symbol with a space |
| R10 | uk_shop | en | GBP | USD 99.99 |
Explicit code that differs from the file |
| R11 | us_ledger | en | USD | 12.5k |
Abbreviated, not a number |
| R12 | us_ledger | en | USD | 1,23.45 |
Separator in the wrong place |
| R13 | us_ledger | en | USD | (blank) | Missing |
R05 and R06 are the reason this post insists on declared locales. The text is identical; the correct amounts differ by a factor of a thousand.
Step 1: Read as text
Read the money column as text. A reader that forces a numeric type will either fail on $1,234.50 or turn the rows it can't parse into missing values; reading as text keeps every value visible until a rule has looked at it. The lesson import everything as text first explains the general rule. In DuckDB use read_csv(..., all_varchar = true); in pandas use dtype="string" and keep_default_na=False.
Step 2: Separate the currency from the amount
Take the currency in this order:
- An explicit three-letter code in the value (
USD 99.99,-1 234,56 EUR). ISO 4217 codes are maintained by SIX on behalf of ISO, and SIX publishes the current list for free (SIX, ISO 4217 data standards), so you can validate codes against it. - An unambiguous symbol:
€is EUR,£is GBP in most business data. - The file's declared currency.
The $ sign is deliberately not in step 2. It's used by the US, Canadian, Australian and several other dollars, so $ on its own can only mean "the file's dollar currency". When a file mixes dollar currencies, $ values belong in a review queue, which is the scenario in the exercise ambiguous symbols need review. The related exercise the file tells you the currency covers taking the currency from file-level metadata.
R10 is worth a second look: a USD amount in a file whose default is GBP. That isn't an error, since shops do take foreign payments, but it's exactly the row that gets summed into the wrong total. Keeping the currency per row is what prevents it.
Step 3: Normalize negative amounts
Detect the sign before you strip characters, because stripping removes the evidence. A value is negative if it is wrapped in parentheses or contains a minus sign. Before checking, replace the Unicode minus sign (U+2212) and the en dash (U+2013) with an ASCII hyphen, because both turn up in copied reports and neither is matched by a plain - in a pattern. The lesson on negative amounts in accounting notation covers the variants in more depth.
One caution: "contains a minus" is safe for single amounts only. If a column can hold ranges like 10-20, require the minus at the start or the end of the value instead.
Step 4: Remove separators by declared locale, then validate
Once the currency and sign are recorded, strip the currency code, symbols, parentheses, minus signs and all whitespace, including the no-break space (U+00A0) and narrow no-break space (U+202F) that European number formats use for thousands. What's left should be digits and separators only.
Now check that shape before converting:
- en:
1,234.50or1234.50. Thousands groups of exactly three digits after a comma, an optional point and decimals. - de:
1.234,50or1234,50. The same with the roles of point and comma swapped.
One gap to know about: because all whitespace is removed first, a space used as a thousands separator isn't checked, so a mistyped 1 23,45 passes as 123,45. If your sources group with spaces and that matters, convert the space to the locale's group separator before the check instead of deleting it.
Only values that pass get their thousands separators removed and their decimal separator turned into a point. 12.5k leaves 12.5k after stripping and fails the shape check. 1,23.45 fails because 23 isn't a three-digit group. Without the check, a "remove everything that isn't a digit or a point" rule would have turned the first into 12.5 and the second into 123.45, both wrong and both silent.
Step 5: Cast to an exact decimal
Cast to DECIMAL, not DOUBLE or float. Binary floating point can't represent most decimal fractions exactly, so 0.1 + 0.2 returns 0.30000000000000004 in both Python and DuckDB's DOUBLE (Python tutorial, Floating-point arithmetic). Over thousands of rows those errors show up as totals that are a cent off. A DECIMAL(18, 4) keeps four decimal places exactly, and 0.1 + 0.2 is 0.3000 (DuckDB numeric types). The guide to money, decimals and rounding goes further into choosing a scale.
Pick the scale deliberately. Four decimals cover most currencies and unit prices, but in DuckDB a cast to DECIMAL(18, 4) rounds anything finer: '12.34567' becomes 12.3457 without an error. pandas behaves differently: on pandas 3.0.2 with pyarrow 22, casting '12.34567' to decimal128(18, 4) raises ArrowInvalid: Rescaling Decimal value would cause data loss instead of rounding. Neither behaviour should be what decides your data, so if the source can carry more decimals, check the decimal count first or use a larger scale. The exercise four-decimal prices, never rounded practises exactly that.
The full rule in DuckDB SQL
WITH s AS (
  SELECT *,
    regexp_replace(coalesce(amount_raw, ''), '[\x{2212}\x{2013}]', '-', 'g') AS a
  FROM amounts
),
parts AS (
  SELECT *,
    CASE
      WHEN regexp_matches(a, '[A-Z]{3}') THEN regexp_extract(a, '([A-Z]{3})', 1)
      WHEN contains(a, '€') THEN 'EUR'
      WHEN contains(a, '£') THEN 'GBP'
      ELSE file_currency
    END AS currency,
    (regexp_matches(a, '^\s*\(.*\)\s*$') OR contains(a, '-')) AS is_negative,
    regexp_replace(a, '[A-Z]{3}|[$€£()\-\s\x{00A0}\x{202F}]', '', 'g') AS core
  FROM s
),
checked AS (
  SELECT *,
    CASE locale
      WHEN 'en' THEN regexp_full_match(core, '(?:[0-9]{1,3}(,[0-9]{3})*(\.[0-9]+)?|[0-9]+(\.[0-9]+)?)')
      WHEN 'de' THEN regexp_full_match(core, '(?:[0-9]{1,3}(\.[0-9]{3})*(,[0-9]+)?|[0-9]+(,[0-9]+)?)')
    END AS shape_ok,
    CASE locale
      WHEN 'en' THEN replace(core, ',', '')
      WHEN 'de' THEN replace(replace(core, '.', ''), ',', '.')
    END AS plain
  FROM parts
)
SELECT id, locale, amount_raw,
  CASE WHEN shape_ok THEN
    CAST(plain AS DECIMAL(18, 4)) * CASE WHEN is_negative THEN -1 ELSE 1 END
  END AS amount,
  CASE WHEN shape_ok THEN currency END AS currency,
  CASE
    WHEN core = '' THEN 'missing'
    WHEN NOT shape_ok THEN 'unparseable amount'
  END AS note
FROM checked
ORDER BY id;
A few details carry the weight. RE2, DuckDB's regex engine, treats \s as ASCII whitespace only, so the no-break spaces are listed by code point. The CASE WHEN shape_ok guard means the cast never sees text that would fail; you could use TRY_CAST instead, which returns NULL on failure, but then a failed parse and a missing value look the same unless you add a note. And the empty value in R13 is wrapped in coalesce(..., '') because DuckDB's CSV reader returns NULL for an empty field.
Output from DuckDB 1.5.1:
id   locale  amount_raw      amount      currency  note
R01  en      $1,234.50        1234.5000  USD       NULL
R02  en      (250.00)         -250.0000  USD       NULL
R03  en      75.00-            -75.0000  USD       NULL
R04  en      −12.40            -12.4000  USD       NULL
R05  en      1,234            1234.0000  USD       NULL
R06  de      1,234               1.2340  EUR       NULL
R07  de      1.234,56 €       1234.5600  EUR       NULL
R08  de      -1 234,56 EUR   -1234.5600  EUR       NULL
R09  en      £ 99               99.0000  GBP       NULL
R10  en      USD 99.99          99.9900  USD       NULL
R11  en      12.5k                 NULL  NULL      unparseable amount
R12  en      1,23.45               NULL  NULL      unparseable amount
R13  en      NULL                  NULL  NULL      missing
R05 and R06 now carry the amounts their sources meant. R11 and R12 are reported, not repaired.
The same rule in pandas
With pyarrow installed (this example imports it anyway), pandas 3 reads text into its Arrow-backed string dtype, and its regex methods on that dtype use the same RE2 syntax as DuckDB, so the patterns carry over unchanged. Without pyarrow, pandas falls back to Python's re, which rejects the \x{2212} escape form; there you'd write \u2212 instead. For the amount, an Arrow decimal type keeps exact values instead of falling back to float64 (pandas ArrowDtype).
import pandas as pd
import pyarrow as pa

df = pd.read_csv("amounts.csv", dtype="string", keep_default_na=False)
a = df["amount_raw"].str.replace(r"[\x{2212}\x{2013}]", "-", regex=True)

code = a.str.extract(r"([A-Z]{3})", expand=False)
df["currency"] = code
df.loc[code.isna() & a.str.contains("€", regex=False), "currency"] = "EUR"
df.loc[code.isna() & a.str.contains("£", regex=False), "currency"] = "GBP"
df["currency"] = df["currency"].fillna(df["file_currency"])

is_negative = a.str.fullmatch(r"\s*\(.*\)\s*") | a.str.contains("-", regex=False)
core = a.str.replace(r"[A-Z]{3}|[$€£()\-\s\x{00A0}\x{202F}]", "", regex=True)

en = df["locale"] == "en"
de = df["locale"] == "de"
shape_ok = (
    (en & core.str.fullmatch(r"(?:[0-9]{1,3}(,[0-9]{3})*(\.[0-9]+)?|[0-9]+(\.[0-9]+)?)"))
    | (de & core.str.fullmatch(r"(?:[0-9]{1,3}(\.[0-9]{3})*(,[0-9]+)?|[0-9]+(,[0-9]+)?)"))
)
plain = core.where(~en, core.str.replace(",", "", regex=False))
plain = plain.where(~de, core.str.replace(".", "", regex=False).str.replace(",", ".", regex=False))

money = pd.ArrowDtype(pa.decimal128(18, 4))
amount = plain.where(shape_ok).astype(money)
df["amount"] = amount.where(~is_negative, -amount)
df.loc[~shape_ok, "currency"] = pd.NA
df["note"] = pd.Series(pd.NA, index=df.index, dtype="string")
df.loc[~shape_ok, "note"] = "unparseable amount"
df.loc[core == "", "note"] = "missing"
On pandas 3.0.2 this returns the same amounts, currencies and notes as the SQL version, with amount typed decimal128(18, 4)[pyarrow]. Avoid pd.to_numeric for this job: it returns floats, and with errors="coerce" it turns every unparseable value into NaN with no record of why.
Totals: per currency, after cleaning
With amounts and currencies in separate columns, the safe total is a group-by on currency:
df.dropna(subset=["amount"]).groupby("currency")["amount"].sum()
currency
EUR       1.2340
GBP      99.0000
USD    2231.0900
Never collapse those into one number without an agreed exchange rate and date, and keep the rate table as data next to the result. The lesson on totals per currency and the exercise sum amounts by currency, without converting practise this step. Three rows were excluded from these totals (two unparseable, one missing), so report that too: a total is only trustworthy next to a count of what didn't make it in.
Frequently asked questions
Can I detect the decimal separator automatically?
Only partly. A value like 1.234,56 has both separators and the last one is the decimal. But 1,234 and 1.234 are ambiguous on their own, and a column can be full of them. Declare the format per source and use detection, at most, as a check that flags files that don't match their declaration.
Should I store amounts in cents as integers?
Integer minor units work when every currency in the column has the same number of decimal places and you never need finer precision. A DECIMAL with an explicit scale is simpler to read and handles unit prices with more decimals. Either way, don't use floats.
What about values like 1.2M or 12.5k?
Treat them as exceptions unless the source documents the abbreviation. If it does, expand them with an explicit rule (k times 1,000) in a separate step, and flag the rows, because an abbreviated value has already been rounded.
How do I handle CR and DR suffixes?
Some accounting exports mark credits with CR instead of a minus. Add it to the sign rule only after confirming with the data owner which side is negative in that system, since the convention depends on the account type.
Practice it
Start with validate currency, then amount, which checks the currency code before the amount, then sum amounts by currency, without converting and the file tells you the currency. For the precision side, try four-decimal prices, never rounded and prices that might be in cents. Each runs in SQL, pandas or the visual pipeline builder.
Related reading
- TRY_CAST in DuckDB: Converting Messy Text Without Breaking Your Query
- Cleaning E-commerce Order Data: A Worked Example
- Why Excel Ruins Your Dates and IDs, and How to Prevent It
Sources
- Unicode CLDR, Number symbols.
- SIX, ISO 4217 currency codes: data standards.
- Python, Floating-point arithmetic: issues and limitations.
- DuckDB, Numeric types and Regular expression functions.
- pandas, ArrowDtype.